RoboCap: A New Platform for Egocentric Robot Learning
In-the-wild, accurate 3D human data 🖐️ for robot foundation models 🤖.
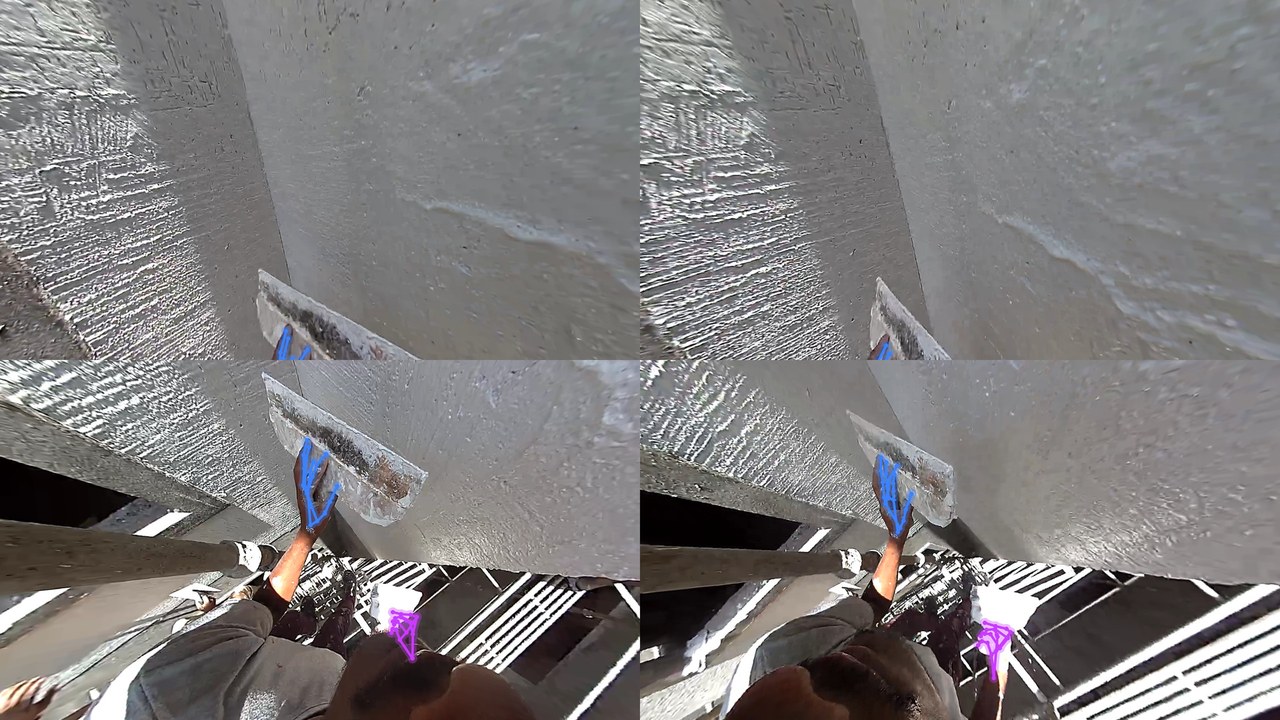
TLDR
We present RoboCap 🎩📷 — a 250 g, six-camera, dual-IMU hat for in-the-wild egocentric data capture — together with the Grounded API, a set of device-agnostic 3D algorithms (SLAM, stereo depth, and hand tracking) tuned for RoboCap. The work was done at Grounded Superintelligence & BitRobot and released as an arXiv Technical Report (2026).
Motivation
Robot foundation models need large amounts of in-the-wild, accurate 3D human data. Egocentric manipulation data is still scarce, and its usefulness is limited by the accuracy of its 3D labels. Collecting it at scale requires ergonomic hardware and precise 3D algorithms to be designed together.
My Role: Lead, Hand Tracking & Self-Calibration
- Hand tracking models: Led training of hand tracking models v1, v2, and v3.
- Self-improving data engine: The model labels in-the-wild video and retrains on it, with no motion capture or human labels. Achieved SOTA on the DexYCB and SHOW3D benchmarks.
- Multi-view geometry: Built the geometry that enables self-distillation: online camera calibration, stereo depth, and multi-camera fusion.
- Deployment: Shipped via the Grounded API, which processes thousands of hours of egocentric video per day.